
More mind per machine
Servamind built a new space for information to live and be computed in. You encode your data once and run your existing models on it: same stack, far more work out of it.
DATA - SERVA ENCODER
Turn raw data into one format any AI system can use
Serva Encoder turns raw data into one lossless, multimodal format — text, images, audio, and sensor data all encode the same way. Prepare data once and use it across training, fine-tuning, and inference. No per-model preprocessing pipeline.
COMPUTE - SERVA CHIMERA
Run your models without rebuilding everything
Chimera lets your existing models run directly on encoded data — [ .SERVA ] in, no retraining, no rebuilds. Accuracy holds while compute, energy, and infrastructure costs drop. Priced at a tenth of the market rate per million tokens.
64 spots remaining
ONE FORMAT, EVERY MODEL
Encode once, run anywhere
Servamind collapses your AI stack into one pipeline. Prepare data once, reuse it everywhere, and stop rebuilding infrastructure at every stage. Your team can ship faster because the system stays simple.
Same accuracy. Far less work.
Maintain model accuracy without changing architectures or retraining models.
Unified
One encoded representation runs across training, fine-tuning, and inference.
Energy Efficient
Reach the same model accuracy while dramatically reducing compute and data movement.
Compatible
Maintain model accuracy without changing architectures or retraining models.
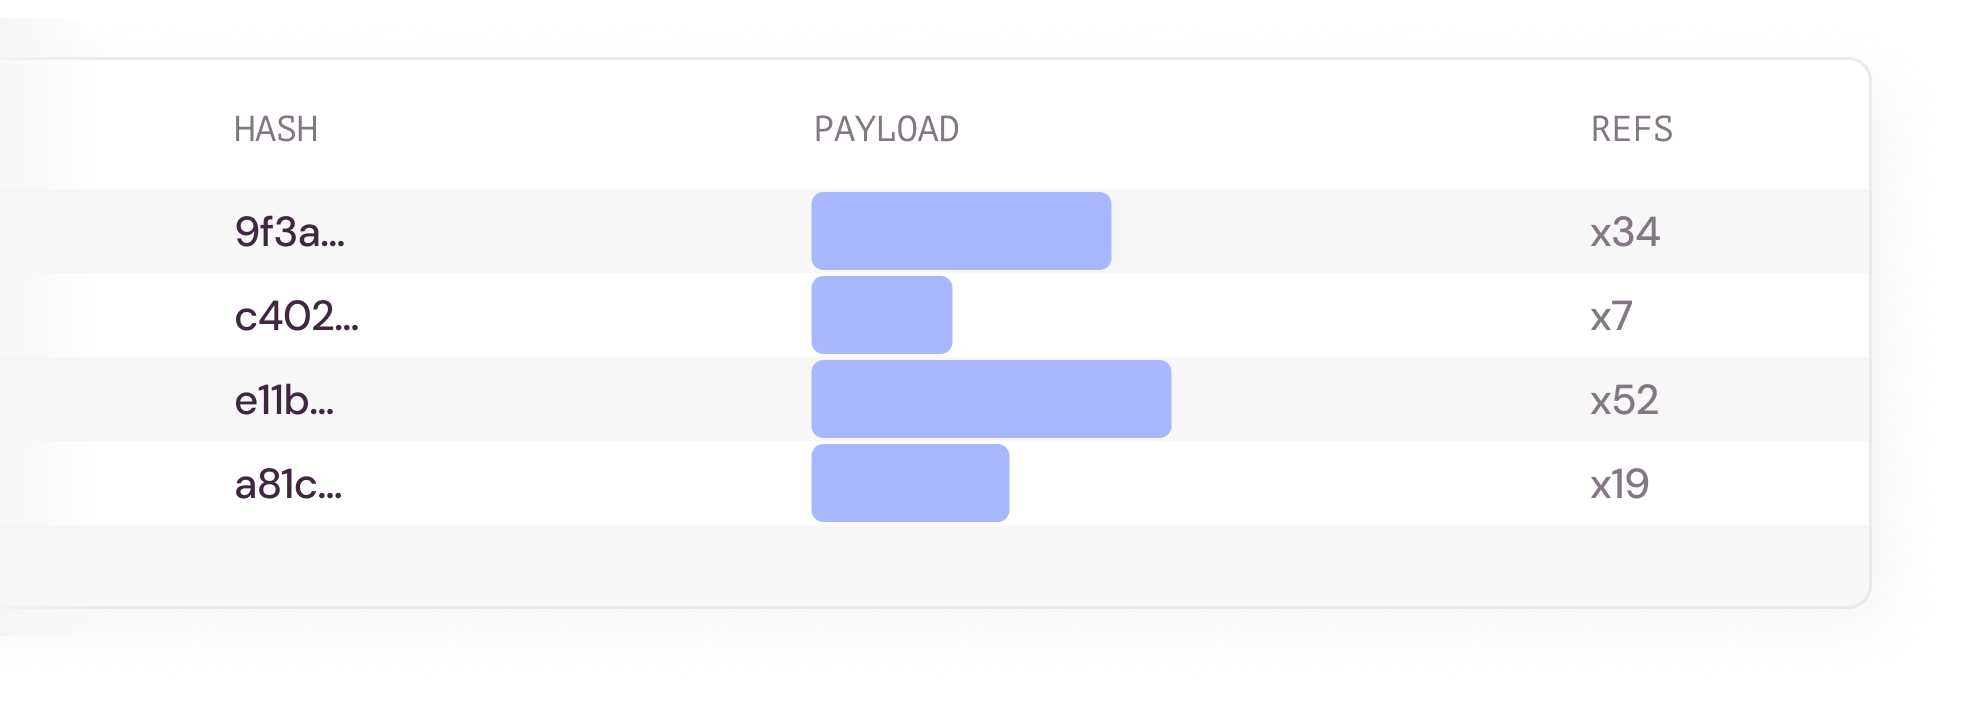
Payload Reduction
Cut the redundant data movement in every training and inference step.
Discord Community
Want to show off what you've built? Stuck on something? Join the Discord.